FinOps Inform
Shift Cost Left: DevOps Cloud Cost Management in 90 Days
A DevOps first FinOps playbook: treat cost as an engineering metric, fix allocation, add CI/CD cost checks and anomaly alerts, and follow a 90 day checklist.
Cloud cost management is the continuous practice of making cloud spend visible, attributable and optimised. If you do one thing this week, fix your allocation metadata and switch on real-time anomaly alerts: everything else in this guide builds on that foundation, including a full 90-day checklist.
TL;DR:
- Most organizations should start by fixing resource tagging, automating cost tracking, and setting up real-time anomaly alerts to prevent waste.
- Ownership models vary between engineering-led, finance-led, and shared councils, with clear responsibilities for tagging, anomaly response, purchasing, and reporting.
- Continuous rightsizing, automated shutdowns for non-production environments, and regular re-evaluation of commitments are essential to control costs effectively.
- Key weekly KPIs to track include allocation coverage, forecasting accuracy, cost savings from early anomaly detection, and cost per business metric.
- Prioritize tools that support multi-cloud data, integrate into existing pipelines, and automate responses, building a 90-day plan to automate, monitor, and optimize cloud spend.
What cloud cost management actually means
Cloud cost management is the ongoing discipline of tracking, attributing and controlling what you spend on cloud infrastructure. Cost optimisation is one part of that, the technical work of rightsizing, committing and eliminating waste. FinOps is the broader operating model that ties engineering, finance and leadership together around shared cost data.
The FinOps Foundation now frames this work as "Cloud+", extending the discipline beyond public cloud into SaaS, licensing, private cloud and data centres, and pushing teams to embed financial context earlier in the build cycle rather than after the bill arrives, as the FinOps Foundation's State of FinOps survey describes. FOCUS, the FinOps Open Cost and Usage Specification, standardises how that cost data looks across providers.
For a DevOps team, that shift changes daily workflow in concrete ways:
- Cost checks run pre-deploy, alongside security and performance gates.
- Tagging is defined and enforced in infrastructure-as-code, not applied after the fact.
- Billing exports are treated as a data source, not a monthly surprise.
Why this matters to engineering and the business
Cost work pays off on both sides of the org chart. For the business, it means predictable budgets, cleaner ROI calculations on infrastructure spend, and a way to prioritise engineering work by financial impact, not just urgency. For engineering, it means less waste sitting in idle resources, faster and better-informed deployment decisions, and clearer ownership when something goes wrong.
Cloud waste remains a persistent problem across the industry. A significant share of cloud spending is estimated to go unused, which is why practitioners are prioritising allocation, forecasting and workload optimisation rather than one-off discount hunting.
None of this requires a finance background. It requires treating cost the way you'd treat latency or error rate: a number you watch, own and act on.
Who owns cloud cost: choosing a FinOps model
Most teams land on one of three ownership models. Engineering-led works when a small platform team already controls infrastructure decisions. Finance-led works when spend is centralised and engineering has limited cloud autonomy. Shared FinOps, run through a small cross-functional council, tends to scale best once multiple teams and multiple clouds are involved.
Whichever model you pick, responsibilities need a clear home:
- Tagging standards and enforcement sit with platform or DevOps engineering.
- Anomaly response and root-cause investigation sit with the team that owns the workload.
- Purchase decisions, such as committing to reserved capacity, sit with whoever owns the budget.
- Reporting cadence sits with a named FinOps lead, even if that's a part-time role.
A FinOps council of five or six people, drawing from platform engineering, finance and one or two product teams, is usually enough to set governance norms: an anomaly response SLA (say, acknowledgement within four hours) and a tagging enforcement policy that blocks non-compliant deployments.
The four capabilities every team needs to build
Cloud financial management breaks down into three pillars, See, Save and Plan, as described in AWS's cloud financial management framework. See covers visibility, ingesting billing data, usage reports and FOCUS-formatted exports so every dollar can be traced to a workload. Save covers waste elimination, rightsizing, commitment management and idle resource clean-up. Plan covers forecasting and budgeting, using historical spend to model what's coming next.
- Visibility: ingest CUR/CER or FOCUS-format billing data and normalise it across providers.
- Allocation: map every cost to a service, account, team and tag, filling gaps with proxy metrics where tagging falls short.
- Anomaly detection: monitor spend continuously against expected baselines, not just monthly totals.
- Governance: enforce tagging and spending policy through automation rather than manual review.
Allocation is the piece teams underrate. Anomaly detection is only useful when it comes with ownership context. The FinOps Foundation's anomaly management capability is explicit that detection without granular allocation, cost by service, account and tag, produces alerts nobody can act on.
Pro Tip: Build allocation before anomaly detection: an alert with no owner attached is just noise with a timestamp.
Rightsizing, autoscaling and other engineering-level fixes
Cost control lives in the same places as performance and reliability work: your CI/CD pipeline and your infrastructure-as-code.
Rightsizing works best as a continuous process, not a quarterly project. Automate collection of rolling utilisation windows (30 days of CPU and memory data is a common baseline) and trigger resizing when a resource sits well below its allocation. Autoscaling, ephemeral test environments and automatic shutdown of non-production resources overnight or at weekends remove a category of waste that manual review rarely catches.
Commitment management, reserved instances or savings plans, needs the same ongoing attention. Workloads evolve, and a commitment purchased a year ago against last year's usage pattern quietly decays into poor utilisation if nobody revisits it.
- Rightsize on a rolling basis using automated utilisation triggers, not manual quarterly audits.
- Autoscale and auto-shut-down non-production environments outside working hours.
- Re-evaluate commitments continuously against current workload shape.
- Use spot or interruptible instances for fault-tolerant workloads, with automated fallback to on-demand capacity.
- Enforce tagging in infrastructure-as-code, with pre-merge checks that reject untagged resources.
Pro Tip: Treat a missing cost tag the same way you'd treat a failing test: block the merge, don't wait for a monthly report to catch it.
The KPIs worth tracking every week
A short KPI set beats a long dashboard. Track allocation coverage (the percentage of spend mapped to an owner), forecasting accuracy (predicted versus actual spend), anomaly-detected cost avoidance (savings from catching issues early) and cost per unit (per request, per customer or per deployment, depending on your business).
Source these from billing exports and infrastructure telemetry rather than manual spreadsheets: a FOCUS-formatted export combined with deployment and usage metrics gives you most of what you need without custom pipelines.
- Allocation coverage: percentage of total spend attributable to a specific team or service.
- Forecasting accuracy: variance between forecast and actual monthly spend.
- Anomaly-detected cost avoidance: dollars saved by catching issues before month-end.
- Cost per unit: spend normalised against a business metric, such as per customer or per transaction.
A well-run anomaly programme should move from detection to resolution quickly, benefiting from advances in energy-efficient AI that help optimise cost and performance together. Implementation typically follows an assessment phase, then quick wins such as shutdowns and rightsizing, then automated monitoring, with measurable savings often visible within 60 to 90 days for many organisations that follow this sequence.
Choosing tools that fit your pipeline, not just your dashboard
Rather than chasing a single all-in-one platform, think in categories: data providers that normalise billing exports, allocation engines that map spend to owners, anomaly detectors, commitment managers, and CI/CD plug-ins that surface cost impact before a deploy ships.
When evaluating any tool in these categories, run it against the same checklist:
- Does it support multi-cloud data, ideally in FOCUS format, rather than locking you to one provider?
- Is it API-first, so it can plug into existing pipelines rather than requiring a separate workflow?
- Does it fit into your developers' existing tools, rather than adding a new dashboard nobody opens?
- Can it automate responses, not just report numbers after the fact?
Integration usually follows a pattern: billing exports feed a normalisation layer, that data flows into allocation and anomaly systems, and CI/CD pipelines call back into cost APIs at build or deploy time to flag risky changes before they ship.
Your first 90 days: a working checklist
Start with what you can see, then automate, then commit.
- Days 0 to 30: run a full inventory of resources and accounts, identify tagging gaps, and execute immediate wins, shutting down idle resources and rightsizing obvious over-provisioned instances.
- Days 30 to 60: automate monitoring and anomaly alerting, add cost checks as CI/CD guardrails, and close remaining tagging gaps through enforced infrastructure-as-code policy.
- Days 60 to 90: revisit commitment purchases against updated usage data, build anomaly response playbooks, and establish a recurring reporting cadence with your FinOps council.
Organisations following this sequence commonly see measurable savings emerge within the 60 to 90 day window, with the earliest wins, shutdowns and rightsizing, typically visible well before that.
What I've learned doing this work
The pattern repeats across every engagement: manual tagging decays within weeks, commitments purchased once are forgotten, and anomaly alerts nobody can attribute get muted within a month. An AI agent can continuously analyse spend and surface where waste is hiding, while specialists help teams actually fix the underlying architecture, not just the bill.
The single behavioural change that helps most: review one cost anomaly in your team's own retro, every sprint, the same way you'd review an incident.
How Koritsu turns this analysis into savings
Most of the waste we find isn't in discount rates. It's buried in how services were architected, provisioned and left running. Our Savings Opportunity Report gives you an engineering-grade view of where that waste sits, backed by our AI platform and hands-on specialists, not a generic dashboard.
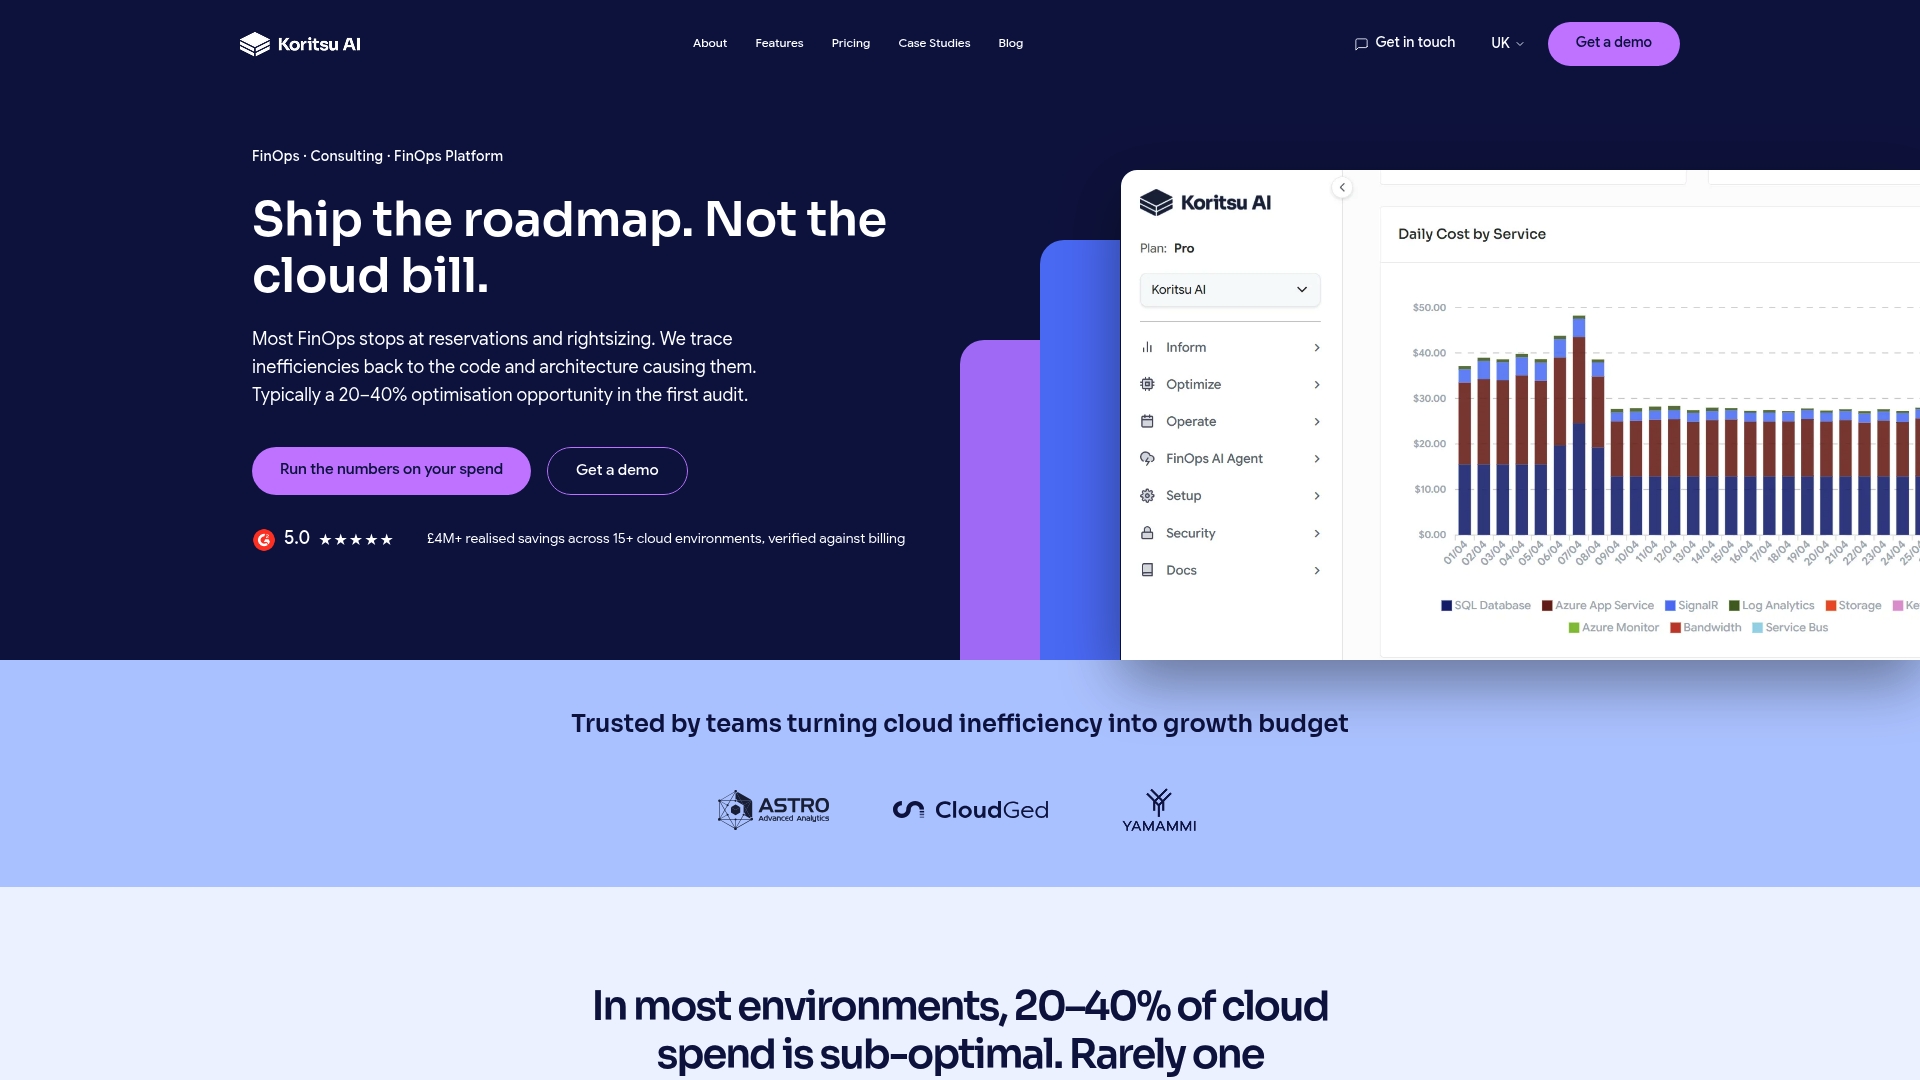
- The Savings Opportunity Report identifies concrete, actionable savings tied to specific services and teams.
- FinOps as a Service, available through Monitor, Advisor, Embedded and Premium plans, provides ongoing platform monitoring and hands-on FinOps support.
- Engagements start with a free assessment, and we take a share of the savings we actually verify against your bill, so there's no upfront cost.
If you'd rather see where your own waste is hiding than keep guessing, start with the Savings Opportunity Report and see what turns up.
Sources
These frameworks underpin the practices covered above and are worth reading directly.
- State of FinOps report (2025)
- FinOps Foundation | State of FinOps survey (press release)
- FinOps Foundation | Anomaly management capability
FAQ
What is cost management in cloud computing?
Cost management in cloud computing is the ongoing practice of tracking, allocating and controlling what an organisation spends on cloud infrastructure. It combines visibility into billing data, attribution of spend to teams or services, and active optimisation such as rightsizing and commitment management.
Is DevOps used in cloud computing?
Yes, DevOps practices, including CI/CD pipelines and infrastructure-as-code, are the standard way teams build, deploy and manage cloud infrastructure. Cost management increasingly integrates directly into these same pipelines, with cost checks run alongside security and performance gates before code ships.
What is cost management in Azure?
Cost management in Azure follows the same principles as any cloud platform: visibility into billing data, allocation of spend by tag or subscription, and optimisation through rightsizing and commitment purchases. Azure-specific tooling exists for this, but the underlying discipline, and standards such as FOCUS, apply across providers.
How do you strategically manage cloud costs?
Strategic cloud cost management starts with allocation, making sure every cost maps to an owner, followed by continuous anomaly detection and rolling rightsizing rather than one-off audits. Pairing this with a clear ownership model and a recurring reporting cadence, as outlined in the FinOps Foundation's framework, keeps the practice sustainable rather than a quarterly scramble.