FinOps Inform
90 Day Engineering Cost KPIs Playbook: FOCUS, Unit Economics, AI
Engineering-first KPI playbook to measure cloud cost with FOCUS, track unit economics, roll out in 90 days, and verify savings with AI.
The engineering cost KPIs that matter most are cost by service, feature and team, cost per customer or unit, allocation completeness percentage, true commitment coverage, cost versus forecast variance, time to react to forecast alerts, and unallocated or waste spend as a percentage of the bill. Tracking this requires normalised cost data and consistent metadata across every provider you use. The rest of this article explains how to measure each one and turn the numbers into action.
TL;DR:
- Normalizing cost data across all cloud providers using the FOCUS schema is essential for accurate KPI calculation and effective cost management.
- Tracking unallocated or waste spend as a percentage of total bill provides a clear indicator of tagging and metadata accuracy, aiming toward zero waste.
- Improving allocation completeness to about 80% at early stages and above 90% at advanced stages ensures more reliable attribution KPIs.
- Regular weekly reviews of cost versus forecast and quick responses to alerts help contain variances and prevent invoice surprises.
- Building unit metrics based on actionable architecture choices allows engineering teams to directly influence cost reductions.
1. Definitive list of engineering cost KPIs
Engineering cost KPIs fall into four groups, and mixing them up is where most FinOps reporting goes wrong. Attribution KPIs answer "who spent it": cost by service, feature and team, measured by tagging or labelling at the resource level and rolled up daily, plus allocation completeness percentage, the share of total spend that can be traced to an owner. Unit economics KPIs answer "is it getting cheaper to serve": cost per customer, cost per transaction, and cost per vCPU-hour, each computed by dividing normalised cost by a business or infrastructure driver pulled from your billing exports and product telemetry.
Optimisation coverage KPIs answer "are we using what we've bought": true commitment coverage and the relationship between covering and covered charges, both of which need contract and usage data at the account level.
Operational KPIs answer "did we stay on plan": cost versus forecast percentage and time to react to forecast alerts, tracked weekly against a rolling forecast baseline.
Hygiene sits underneath all of it: unallocated or waste spend as a percentage of total bill, ideally trending towards zero as tagging improves.
- Attribution KPIs feed engineering team dashboards and performance reviews.
- Unit economics KPIs feed product and pricing conversations with finance.
- Coverage and forecast KPIs feed monthly FinOps and budget reporting.
- Waste percentage is the single number worth putting on every team's home page.
Engineering teams should own the attribution and unit economics numbers directly. Coverage and forecast KPIs are better shared ownership between platform engineering and finance, since neither group can move them alone.
2. Normalising cost data before you calculate KPIs
None of these KPIs mean anything if the underlying cost data is inconsistent between AWS, Azure and Google Cloud. The FOCUS specification exists precisely for this: a provider-agnostic schema covering Cost and Usage and Contract Commitment datasets, so a vCPU-hour or a commitment discount means the same thing regardless of which cloud generated it. Normalise first, then calculate.
Three steps get you there:
- Turn on daily cost and usage exports from every provider and land them in one repository.
- Map each provider's billing fields to the FOCUS schema, prioritising Billed Cost and Effective Cost columns.
- Reconcile exports against the actual invoice each month to catch drift before it compounds.
FinOps guidance suggests targeting high levels of allocated spend at "Walk" and "Run" maturity stages, giving teams a concrete goal for tagging and metadata rather than an open-ended tidy-up project. Use amortised or effective cost rather than billed cost wherever KPIs involve commitments: billed cost spikes in the month you buy a reservation, while effective cost spreads the benefit across its actual usage, which is what engineering decisions should respond to.
3. Attribution and unit economics that engineers can act on
Tag-based allocation works for anything a single team owns outright: a service, a database, a queue. Shared infrastructure needs a different approach. For a Kubernetes cluster running multiple teams' workloads, split cost by CPU and memory requests rather than by pod count, since idle capacity otherwise gets attributed to nobody. For multi-tenant services, use a splitter metric such as request volume or storage consumed per tenant, then apply that ratio to the shared infrastructure line.
- Cost per transaction needs event-level telemetry, not just infrastructure logs.
- Cost per customer needs a reliable customer identifier joined to usage data.
- Cost per vCPU-hour needs instance-level billing joined to utilisation metrics.
Pro Tip: Build the splitter metric into your application's existing metrics pipeline rather than a separate cost tool, so the ratio updates automatically as usage patterns shift.
Pick unit metrics engineers can actually influence through architecture choices, not vanity numbers that move only when the business grows.
4. Forecast accuracy and how fast teams respond to alerts
Cost versus forecast percentage is the gap between what you predicted and what the provider billed, and it should be reviewed weekly, not monthly, so problems surface before the invoice does. Azure's cost management guidance recommends tracking time to react to forecast alerts as its own KPI, distinct from accuracy itself, because a team that spots an anomaly fast can contain it even when forecasting is imperfect.
Not every variance is bad news: a planned load test or a deliberate scale-up should be tagged separately from genuine drift, since treating all variance the same way hides the signal you actually need.
- Set alert thresholds at 10 to 15% above forecast rather than waiting for month-end.
- Tag planned variance at the point of decision, not after the invoice lands.
- Pair every alert with an automated mitigation: autoscaling limits, scheduled shutdowns, or a runbook trigger.
5. Commitment coverage and discount KPIs
True commitment coverage is the percentage of eligible usage actually running against a reservation or savings plan, and it only becomes calculable once you separate covering charges (what you paid for the commitment) from covered charges (the usage it offset). The FOCUS specification's Contract Commitment fields make this pairing computable across providers rather than provider by provider.
Report coverage using effective cost, not billed cost, since billed cost distorts the picture in the month a commitment is purchased.
- Compare utilised commitment hours against total commitment hours to spot under-used reservations, a check AWS Well-Architected guidance recommends directly.
- Flag any commitment sitting below 80% utilisation for review before renewal.
- Check marketplace covering and covered charge pairs monthly for mismatches.
6. Turning KPI trends into engineering action and verified savings
Each KPI points to a specific lever. Rising cost per vCPU-hour usually means right-sizing is overdue. Falling commitment coverage means autoscaling policies changed usage patterns faster than purchasing kept up. Rising waste percentage often traces back to workload placement or orphaned resources.
- Right-sizing moves cost per vCPU-hour and unallocated waste percentage.
- Autoscaling policy changes move cost versus forecast and commitment coverage.
- Caching and batching move cost per transaction directly.
- Feature flags let you isolate cost per feature before a full rollout.
Pro Tip: Always capture a baseline period before an intervention and hold it steady, so the post-change measurement window is comparing like with like rather than a different traffic pattern.
Verify every claimed saving against the actual invoice, not the estimate, and credit it to the team or feature that made the change so the KPI dashboard reflects real ownership rather than platform-wide averages.
7. Rolling out engineering cost KPIs in 90 days
A phased rollout avoids the common trap of trying to report perfect KPIs before the data is ready.
- Days 1 to 30: ingest exports, normalise to FOCUS, and assign tagging owners across platform and engineering.
- Days 31 to 60: hit an allocation completeness baseline and compute first-pass KPI values.
- Days 61 to 90: run one optimisation sprint per team and verify savings against the bill.
| Milestone | Owner | KPI published |
|---|---|---|
| Day 30 | Platform/FinOps | Allocation completeness % |
| Day 60 | Engineering | Cost by team/feature, cost per unit |
| Day 90 | Engineering/Finance | Cost vs forecast %, verified savings |
Report cost by team and unit economics monthly to engineering leadership, and reserve commitment coverage and forecast accuracy for quarterly finance reviews, where trend matters more than a single month's noise.
Why most FinOps dashboards miss the point
Most FinOps tooling treats cost as a reporting problem: build a dashboard, colour the bars, send the email. That approach produces KPIs nobody argues with and nobody acts on either, because a dashboard cannot tell an engineer which line of infrastructure-as-code to change.
The uncomfortable truth is that the highest-value savings rarely come from buying better discounts. They come from architectural decisions made months or years earlier: a synchronous call that should be batched, a cluster sized for peak load that never arrives, a cache that was never turned on. Cost is not a technology problem, it is a process problem, and KPIs only earn their keep when they route straight to the engineer who can fix the underlying design.
Treat allocation completeness and waste percentage as leading indicators, not vanity metrics.
Free assessment and a success-fee model
Cloud savings can be found by tracing spend to the architecture and software decisions that caused it, not just the discounts you did or didn't buy. An AI agent can analyse cost data continuously, and specialists can help teams act on what it finds.
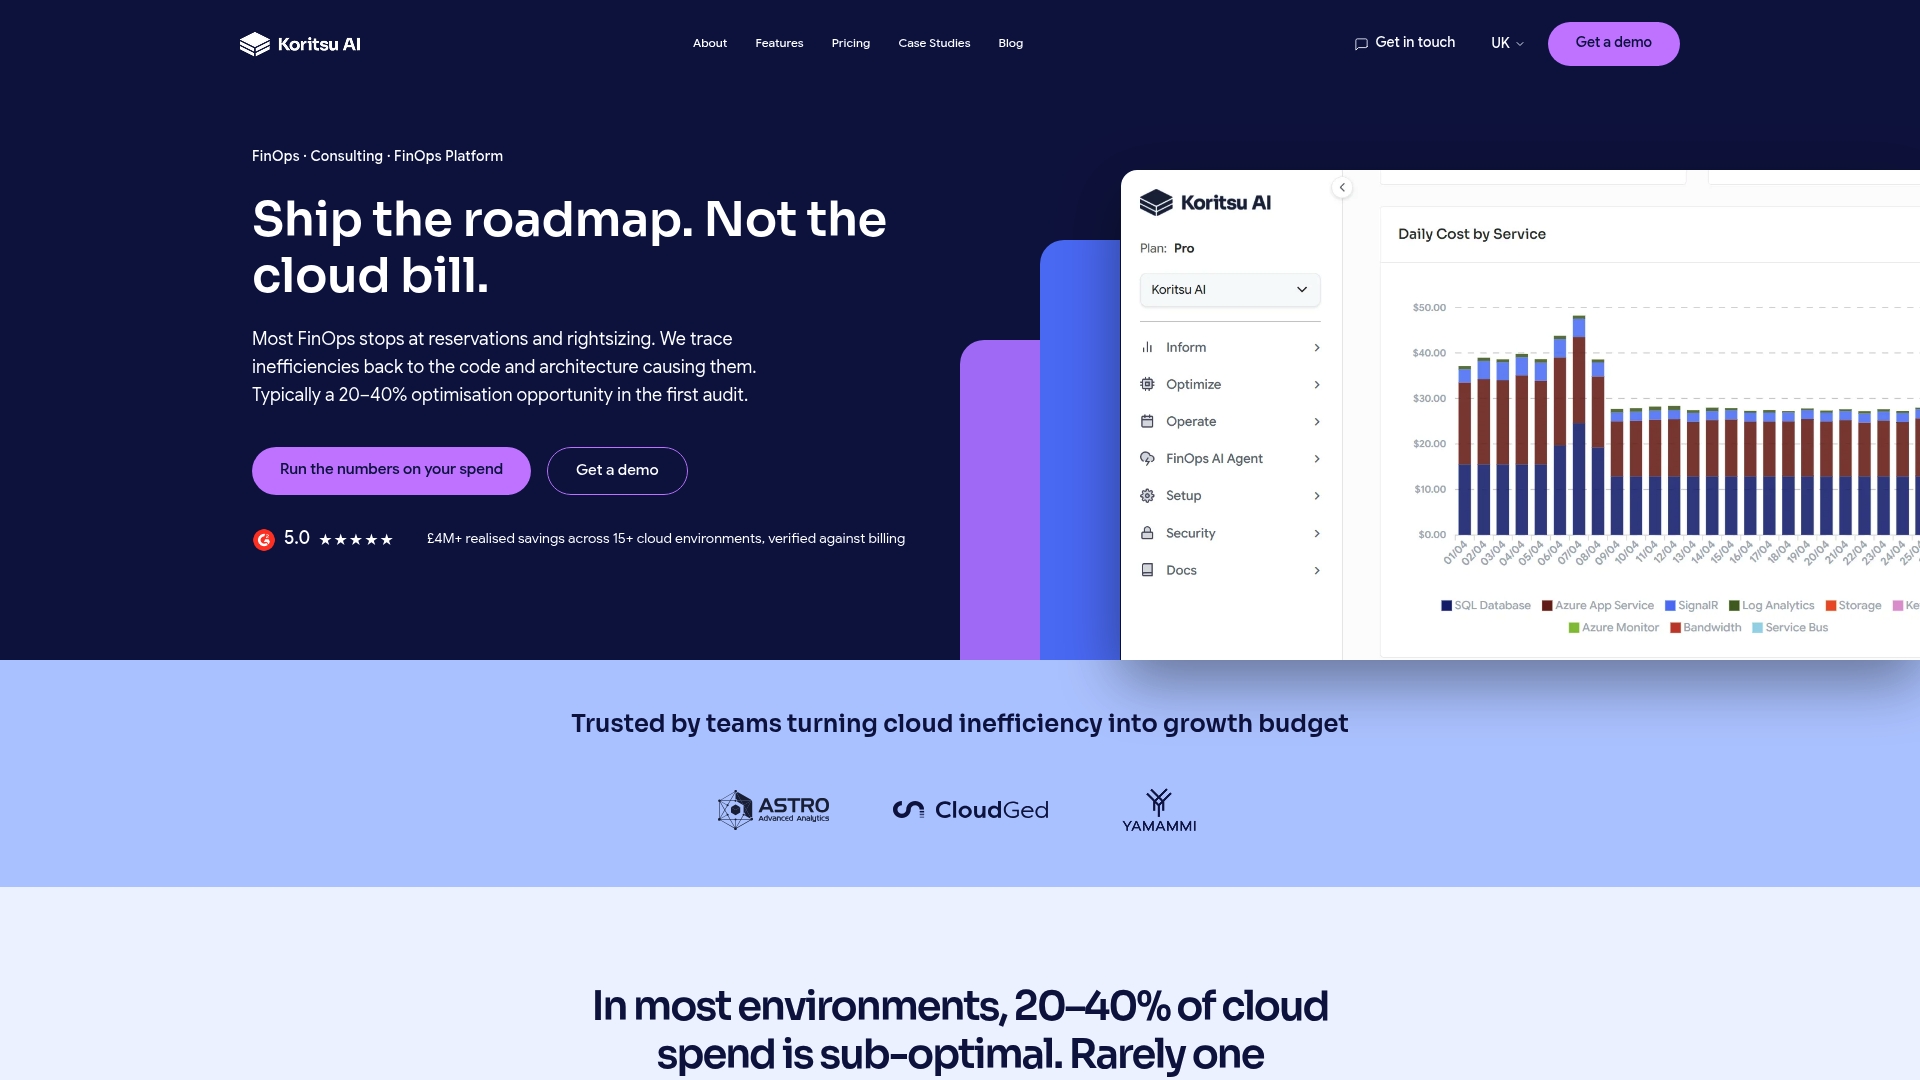
Every engagement starts with a Savings Opportunity Report, a free assessment that identifies concrete savings before you commit to anything. We charge a share of the savings we actually verify on your bill, detailed on our pricing page, and teams that want ongoing coverage can move onto FinOps as a Service, available as Monitor, Advisor, Embedded or Premium.
Sources
For teams building this out internally, these are the primary references behind the KPIs above: the FinOps Framework's KPI library for benchmarking guidance, the FOCUS specification for cross-cloud data normalisation, and provider guidance from AWS and Microsoft Azure on forecasting and cost review. Finance teams building rolling budgets around these KPIs may also find value in outsourced finance advisory support such as Keystone Financial Advisory.
- AWS Well-Architected cost optimisation pillar
- FinOps Foundation | cost allocation guidance
- FOCUS specification | supported features (v1.4)
- Azure well-architected cost optimisation: collect and review cost data
FAQ
What is the most important engineering cost KPI to start with?
Allocation completeness percentage is the best starting point, since every other KPI depends on knowing who owns the spend. Without it, cost by team, unit economics and waste percentage are all guesses.
How is true commitment coverage different from billed cost coverage?
True commitment coverage measures utilised commitment hours against total commitment hours using effective cost, while billed cost coverage can look artificially high or low depending on when a commitment was purchased. The FOCUS specification's Contract Commitment fields make the effective-cost version calculable across providers.
What allocation completeness percentage should we aim for?
FinOps guidance points to roughly 80% allocated spend at "Walk" maturity, rising to around 90% at "Run" maturity. Treat these as staged benchmarks rather than a single pass or fail line.
How often should cost versus forecast be reviewed?
Weekly review catches drift before it reaches the invoice, which is the point of tracking time to react to forecast alerts as a separate KPI. Monthly review alone tends to surface problems too late to act on cheaply.
Does Koritsu charge upfront for a cost assessment?
No, the initial Savings Opportunity Report is a free assessment, and Koritsu's fee is a share of the savings verified against your actual bill afterwards.