FinOps Inform
Stop Forecast Misses: 5 Cost Forecasting Models FinOps Teams Use
Practitioner FinOps guide to picking and running cost forecasting models. Covers the rolling driver-based default, accuracy benchmarks, and practical governance.
Cost forecasting predicts what you will spend based on historical patterns, business drivers and known future events, and it differs from a budget or an estimate because it updates continuously as new data arrives. There are five main model families: trend and time series, driver-based, regression, probabilistic, and machine learning. For most organisations running variable cloud workloads, the practical starting point is a rolling driver-based forecast layered on a trend baseline for stable infrastructure.
TL;DR:
- Most cost forecast failures result from poor governance, such as unowned spend, misclassified commitments, and lack of explicit special projects tracking.
- Continuous, automated spend analysis helps catch anomalies early, improving forecast accuracy and enabling timely actions like rightsizing resources.
- Using driver ownership, creating separate lines for commitments and projects, and setting fixed review cadences are critical for reliable, actionable forecasts.
- A rolling driver-based forecast paired with a trend baseline is suitable for most organizations, especially for customer-facing cloud workloads.
- Forecast accuracy targets should align with organizational maturity, with 10-12% MAPE achievable for advanced teams and higher variances acceptable early on.
What is cost forecasting, and how is it different from budgeting?
Cost forecasting, budgeting, and estimating get used interchangeably in most finance meetings, and that sloppiness causes real problems. Each one answers a different question, and mixing them up leads to forecasts that get treated as promises, or budgets that never adjust when reality shifts.
A forecast predicts what you will actually spend, based on current trends and known changes. It updates regularly, sometimes weekly, and it is meant to be revised. A budget is a target or a constraint, set once for a period (usually a quarter or a year) and used to hold teams accountable. An estimate is a one-off prediction for a specific initiative, like the cost of migrating a database or launching a new product line. It is not meant to be tracked over time the way a forecast is.
Getting this distinction right changes how you build the model. A forecast needs to flex with new inputs. A budget needs to hold still long enough to plan against it. Confusing the two is why so many finance teams end up arguing about "forecast accuracy" when what they are really measuring is whether engineering stayed under a number set eight months earlier.
Horizons matter too, and different questions need different windows:
- Short-term (weekly to monthly): used for operational alerting and catching anomalies before they compound.
- Rolling 12-month: the workhorse view for FinOps teams and infrastructure leaders, updated monthly as drivers change.
- Annual: used for board reporting, procurement negotiations, and headcount planning.
Finance teams use forecasts to negotiate committed-use discounts before renewal windows close. Engineering leaders use them to decide whether rightsizing work is worth the effort. Executives use them to steer budget allocation across competing priorities. If your forecast only serves one of these audiences, it is probably too narrow.
What goes into a reliable cost forecast?
A forecast is only as good as what feeds it, and most inaccurate forecasts trace back to the same handful of input problems rather than a badly chosen model. Get the inputs right first.
- Amortised, discount-adjusted billing data. Raw invoice totals distort trends because they mix in upfront reserved-instance payments and one-off commitments. Microsoft's FinOps guidance recommends using amortised cost views so that spend gets spread evenly across the period it actually covers, giving you a comparable baseline month to month.
- A driver inventory with named owners. Every meaningful cost swing has a cause: a new customer cohort, a marketing campaign, a deprecated service, an exchange rate movement. Log each driver with a date, an owner, and a quantified expected impact. Drivers without owners are just guesses with better formatting.
- Complete scope and allocation. Forecasts built on partially tagged spend will always underestimate, because the untagged portion grows invisibly. Map cost to application, team, environment and namespace before you trust the trend line.
- Separate lines for commitments and special projects. Reserved capacity purchases and one-off migrations behave nothing like steady-state usage. Blending them into the main forecast line hides both the risk and the opportunity.
- Versioning and a fixed review cadence. A forecast nobody revisits monthly is a historical document, not a forecast. Assign a governance owner and a standing review slot.
Skip any one of these and the model you choose barely matters. The FinOps Foundation frames this as a maturity progression, not a one-time setup task, because the inputs improve gradually as an organisation's practices mature.
Which cost forecasting models should you actually use?
Model choice comes down to three questions: how much clean historical data do you have, how far out do you need to see, and how much does the business need to understand why the number is what it is. Here is how the main families answer those questions differently.
Time series and trend models (moving average, exponential smoothing, ARIMA) look purely at historical spend and project it forward. They need very little setup, work with as little as a few months of clean data, and are fast to build. Their weakness is obvious the moment something changes: a new product launch, a migration, or a pricing change will not show up in a trend model until it has already happened. NetSuite's breakdown of forecasting methods groups these under quantitative techniques, alongside regression, and notes they work best when the underlying pattern is genuinely stable.
Driver-based models map spend to business metrics, active users, API calls, transaction volume, and encode the dated ramps you already know about. This is the model that tends to win stakeholder trust fastest, because when spend jumps, you can point to the driver that caused it rather than shrugging at a chart. It takes more setup work than a trend model, since you need a defensible relationship between the driver and the cost, but it scales far better for workloads that are actually growing.
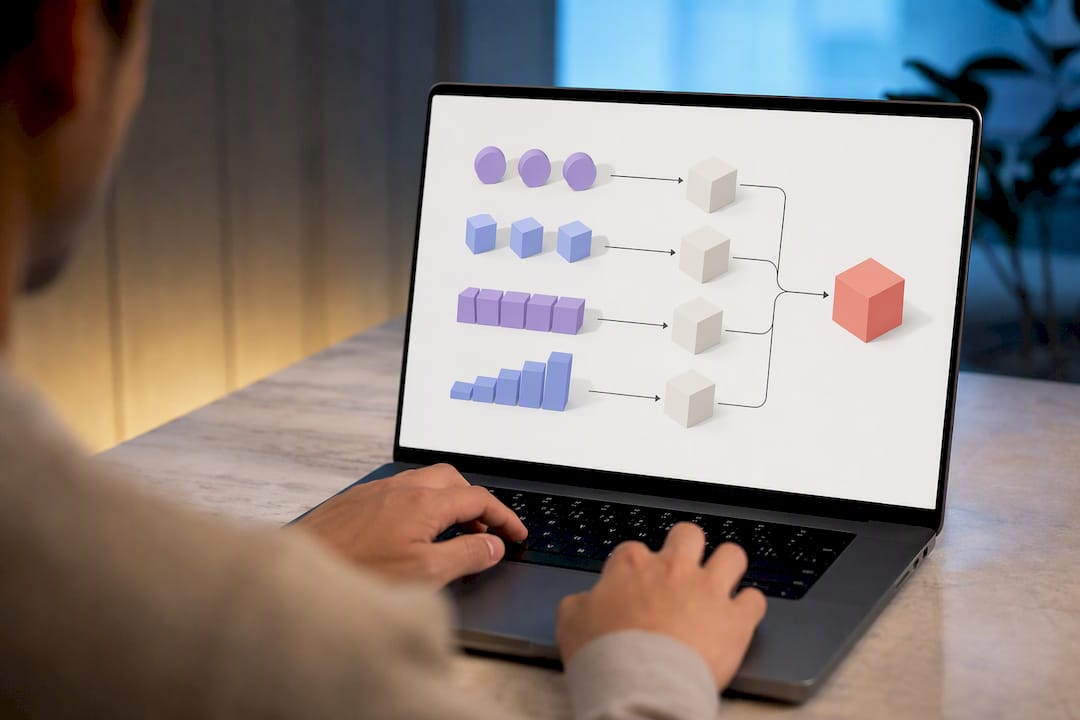
Regression and econometric models go a step further and quantify causal relationships between spend and external variables, exchange rates, interest rates, seasonal demand, headcount growth. Workday's roundup of financial forecasting models lists regression alongside straight-line and scenario approaches, and notes it earns its complexity when multiple factors genuinely move the number together. If your cloud spend correlates with marketing campaign timing or seasonal traffic, regression will surface that link explicitly instead of burying it in a trend.
Probabilistic models, Monte Carlo simulation and interval forecasting, produce a range and a confidence level instead of a single number. This matters enormously for procurement decisions, where you need to know the worst-case exposure before committing to a three-year reserved capacity deal, not just the expected midpoint. Recent research into hybrid probabilistic ensembles, the NGBoost-ETR framework, shows that combining gradient boosting with probabilistic layers can deliver both strong point accuracy and well-calibrated intervals, which historically has been a trade-off rather than a package deal.
Machine learning and ensemble models earn their place only when you have large volumes of clean, labelled historical data and genuine non-linear patterns worth capturing. They are harder to explain to a finance committee, which is why interpretability tools like SHAP matter here. Without them, an ML forecast becomes a black box that nobody trusts enough to act on.
Pro Tip: Do not reach for machine learning because it sounds more rigorous. A driver-based model that a finance director can explain in one sentence will get acted on faster than an ensemble model nobody in the room fully understands.
How do you choose the right forecasting model?
Match the model to what you actually have, not to what looks impressive in a slide deck. A rough decision matrix:
- Limited history, stable platform: trend or time series model. Fast to stand up, adequate for platform costs that do not change shape month to month.
- Moderate history with identifiable growth drivers: driver-based model. This covers most customer-facing product infrastructure.
- Multiple external variables genuinely moving spend: regression or econometric model.
- Procurement or budget-risk decisions that need a confidence range, not just a midpoint: probabilistic model.
- Large, clean, labelled datasets with a genuine non-linear relationship: ML or ensemble, with interpretability tooling built in from day one.
For most organisations, the sensible default is a rolling driver-based forecast for anything customer-facing, sitting alongside a trend baseline for platform-level infrastructure that does not scale with usage. This combination covers most of the estate without demanding data science resourcing you may not have.
A few signals tell you it is time to upgrade. If you are consistently missing your MAPE target despite clean inputs, the model itself may be the constraint. If governance has matured to the point where multiple teams rely on the same forecast, versioning and driver-based structure become non-negotiable. If procurement now needs a confidence interval rather than a single number, that is the trigger to add a probabilistic layer rather than replacing what already works.
How do you build a cost forecast step by step?
Building a forecast that survives contact with a real finance review takes more than picking a model. It takes a repeatable process.
- Define scope and owners. Decide which cost pools you are forecasting (a single cloud account, a product line, the whole estate) and name a single accountable owner.
- Collect 12 to 18 months of normalised billing data, using amortised cost wherever possible so upfront commitments do not distort the trend.
- Filter out one-off purchases and deleted resources. These create false spikes and false floors that will mislead any model trained on them.
- Create an explicit special projects line for planned launches, migrations, or seasonal campaigns, separate from steady-state usage.
- Capture drivers with a date, an owner, and a quantified expected delta. Encode ramp schedules rather than treating growth as instantaneous.
- Select a base model, backtest it against known history, and measure MAPE or WAPE against actuals. Iterate the model choice based on what the error tells you, not on preference.
- Operationalise the forecast. Set up daily data ingestion, a monthly forecast review meeting, forecast-first alerting (flagging deviations from the forecast, not just from last month's actuals), and a fixed variance review cadence.
Microsoft's Azure cost management guidance recommends subscribing to scheduled and anomaly alerts rather than checking dashboards reactively, which turns forecasting from a monthly report into a running early-warning system.
Pro Tip: A five-minute standing item in your sprint planning or team stand-up, "is anything landing next month that changes our cloud footprint?", catches more forecast-breaking surprises than any dashboard. Encode the answer as a dated driver the same day.
What forecast accuracy should you aim for?
MAPE (Mean Absolute Percentage Error) and WAPE (Weighted Absolute Percentage Error) are the two metrics that matter most. MAPE averages the percentage error across periods; WAPE weights larger cost pools more heavily, which usually gives a fairer picture when spend is concentrated in a handful of services. Average that across twelve months and you have your MAPE.
The FinOps Foundation ties acceptable variance to organisational maturity rather than treating one number as universal. Its benchmarks: Crawl stage teams should target roughly 20% variance, Walk stage around 15%, and Run stage organisations should be tightening toward 10 to 12%. Treat these as directional targets tied to your governance maturity, not hard pass/fail thresholds, since a team with patchy tagging has no business chasing a Run-stage number.
Beyond the headline accuracy figure, track forecast versus actual by cost pool (not just in aggregate), the count of unexplained anomalies per month, and the average time between an alert firing and someone actually investigating it. That last metric often reveals more about your operational maturity than the accuracy number itself.
What usually breaks a cost forecast?
Most forecast failures trace back to the same recurring causes, and nearly all of them are process problems rather than modelling ones.
- Unallocated spend that nobody owns tends to grow quietly until it distorts the whole trend. Assign an interim owner the moment you spot it, even before the permanent tagging fix ships.
- Commitment accounting mismatches happen when reserved-instance or savings-plan payments get treated as regular usage instead of being amortised, creating false spikes in the month they were purchased.
- Blind spots around new launches are almost inevitable if special projects sit inside the main forecast line instead of their own explicit row updated by engineering each month.
- Overfitting shows up when a complex model chases noise in historical data rather than the underlying pattern. An interpretable model that is slightly less accurate but explainable will outperform a black box nobody trusts enough to act on.
- Escalation gaps turn small variances into large surprises. A clear rule for who gets alerted, and when, prevents a 15% miss from becoming a 40% one three months later.
How does continuous monitoring change forecast accuracy?
Forecasts degrade fastest when the driver inventory goes stale, and that is usually a resourcing problem rather than a modelling one. Nobody has time to manually review every service's spend pattern every week.
This is where continuous, automated analysis earns its keep. Instead of waiting for a monthly review to catch a spend anomaly or an inefficiency that has been quietly accumulating, an always-on monitoring layer surfaces it the week it appears, with a date attached, which turns it directly into a forecast driver rather than a retrospective explanation.
Continuous analysis of cloud spend that flags architectural inefficiencies and anomalies as they happen, dated and quantified, ready to feed straight into a driver-based model. A few things this changes in practice:
- Optimisation work (rightsizing, deleting orphaned resources, fixing autoscaling misconfigurations) gets logged as a dated delta rather than showing up as an unexplained dip weeks later.
- Anomalies get caught close to when they start, shrinking the gap between alert and investigation that most FinOps KPI dashboards measure.
- Teams that keep their forecasting model in-house can still use external expertise to accelerate governance maturity, without handing over the whole process.
Some cloud cost optimization providers start engagements with a free assessment and charge only as a share of the savings found, to keep incentives aligned with genuinely improving your numbers rather than billing hours.
What should teams change first?
If you take one thing from all of this, make it driver ownership. Most forecasting failures I see are not modelling failures. They are governance gaps: nobody assigned an owner to a driver, nobody dated the ramp, nobody built a special projects line, so the forecast quietly rots the moment reality diverges from the trend it was built on.
Do three things in the next 90 days: name an owner for every material driver, create an explicit special projects line separate from steady-state spend, and switch your alerting from actual-first to forecast-first so deviations surface before they compound. None of this requires new tooling. It requires someone deciding it matters enough to maintain.
Want an assisted route to a sharper forecast?
If building and maintaining driver ownership internally feels like more governance overhead than your team has capacity for right now, Koritsu AI's Savings Opportunity Report gives you a faster starting point.
The report combines a full assessment of your cloud estate with the specific inefficiencies our AI agent Kori surfaces, each one dated and quantified the way a driver-based forecast needs. You get concrete, ranked savings opportunities and suggested ramp dates for acting on them, the exact inputs your next forecast revision would otherwise take weeks to gather manually. Because pricing is performance-based, charged only as a share of savings we verify against your actual billing, there is no upfront cost to finding out what is buried in your architecture. If your forecast keeps missing because unexplained spend keeps showing up, that is usually the fastest way to find out why. Request the free assessment and see what surfaces.
Sources
Every forecast worth trusting starts with the same raw materials, regardless of which model sits on top of them.
- Forecasting - FinOps Foundation
- Forecasting guidance - Microsoft / FinOps framework (Azure docs)
- What Is Cost Forecasting? Benefits & Best Practices - NetSuite
- Top 7 types of financial forecasting models - Workday blog
FAQ
What are the four main types of forecasting models?
Most frameworks group forecasting into trend or time series models, driver-based models, regression or econometric models, and probabilistic models, with machine learning increasingly used as a fifth category where data volume justifies it.
What are the different types of cost models used in business?
Cost models generally fall into quantitative approaches (time series, regression), qualitative approaches (expert judgement, scenario analysis), and causal approaches that tie spend to specific business or external variables, as NetSuite's breakdown sets out.
What is the best model for forecasting cloud costs?
There is no single best model; a rolling driver-based forecast layered on a trend baseline works well for most organisations, while probabilistic models add value specifically when procurement or budget decisions need a confidence range rather than a single figure.
What methods are used to forecast costs?
Common methods include moving averages and exponential smoothing, driver-based modelling tied to business KPIs, regression against external variables, Monte Carlo simulation for probabilistic ranges, and machine learning ensembles when data volume and quality support it.
How accurate should a cost forecast be?
Accuracy targets should scale with your governance maturity: the FinOps Foundation suggests roughly 20% variance for early-stage teams, 15% for intermediate maturity, and 10 to 12% for advanced FinOps practices.